RLHF Preference Dataset
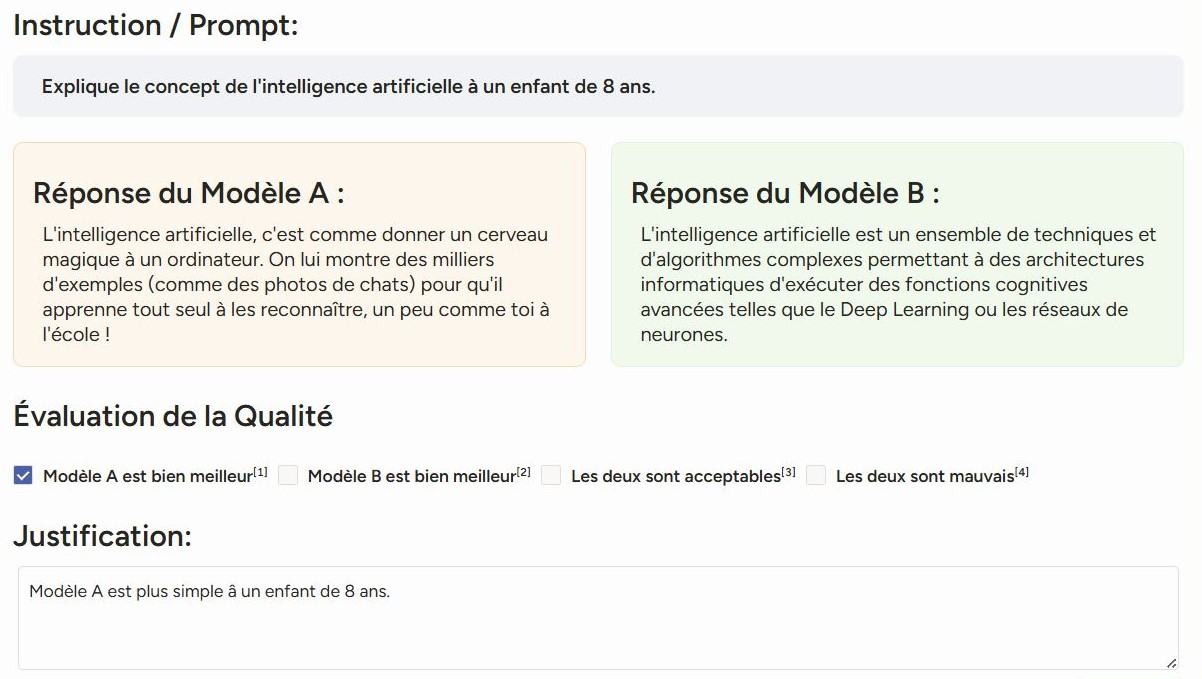
Side-by-side model comparison interface — annotators weigh Model A against Model B across a real prompt, select a preference tier, and record written justification for every judgment.
Conversational AI
RLHF Human Preference Evaluation Dataset
A large set of human preference pairs across dozens of domains for LLM alignment — covering helpfulness, harmlessness, and factuality dimensions.
The Challenge
Judging which of two model responses is "better" is inherently subjective, and preferences can vary widely across annotators and domains. The task required capturing nuanced human judgment — not just surface-level fluency or length — across dozens of different domains, while avoiding common annotator biases (favoring longer or more confident-sounding answers) and keeping judgments consistent at scale across a large volume of comparisons.
Our Solution
Annotators reviewed each prompt alongside both model responses side-by-side and selected one of four preference tiers — Model A much better, Model B much better, both acceptable, or both poor — then wrote a short written justification explaining the judgment for every single comparison. Inter-annotator agreement was tracked continuously using Cohen's Kappa; any batch scoring below the required agreement threshold triggered recalibration with the annotation team before work continued.
The Deliverables
A large set of labeled preference pairs spanning dozens of domains, each with a written justification for interpretability · Structured JSON output ready for RLHF and DPO fine-tuning pipelines · Full inter-annotator agreement scoring included alongside the dataset.